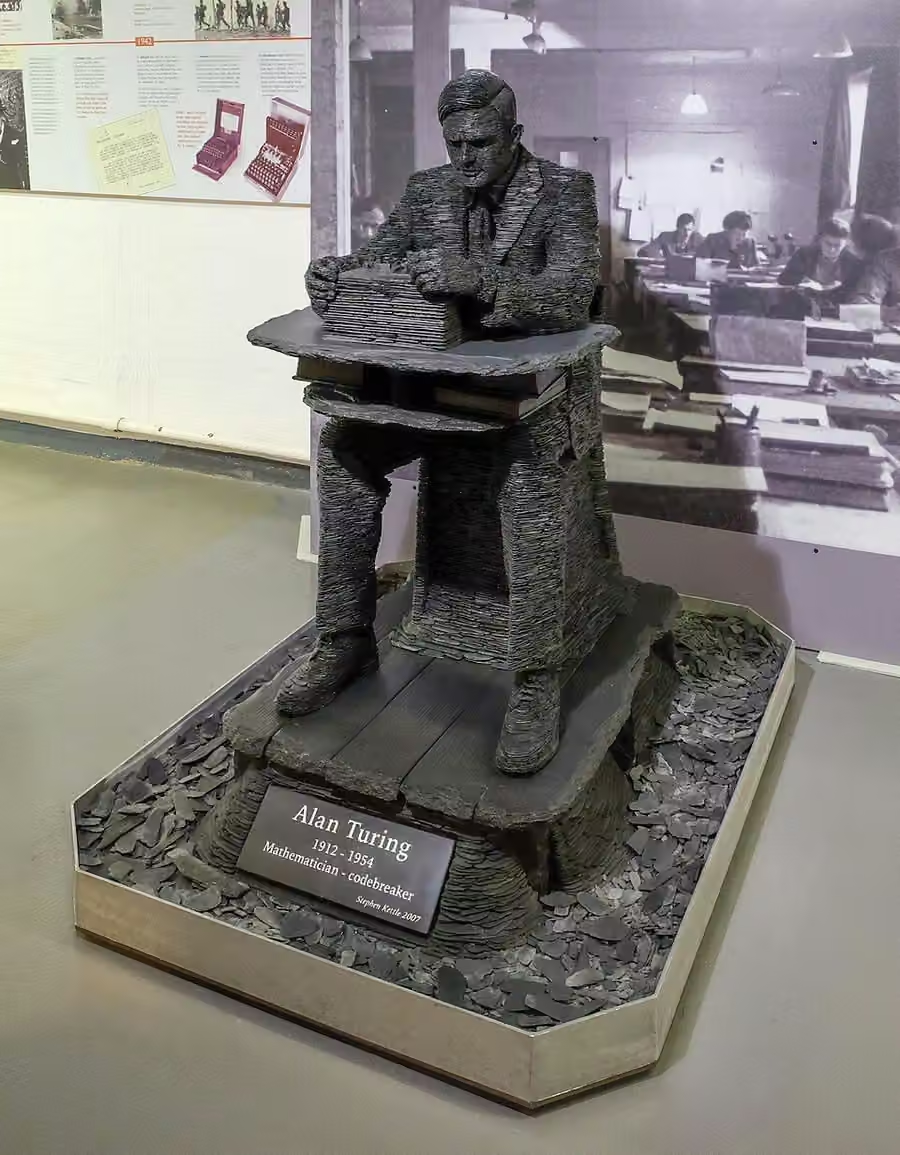
What Turing proposed
Turing's imitation game placed a machine in a text-only conversation with an interrogator, alongside a human. If the interrogator could not reliably identify the machine, Turing proposed we treat the question of machine thinking as answered in the affirmative.
The proposal was deliberately operational: it replaced a metaphysical question with a behavioural one. Turing predicted that by about 2000 a machine would fool an average interrogator for five minutes, and he was roughly right about the date and wrong about what it would mean.
What has happened since
The Loebner Prize ran annual competitions from 1991 with a bronze medal for the most human-seeming program; none of the winners was remotely intelligent, and the contest was criticised for rewarding deception rather than understanding.
Modern language models changed the picture. Studies in 2023 and 2024 found that participants could not reliably distinguish a current chatbot from a human in short conversations, and often assumed the human was the machine — the ELIZA effect, in which fluent text is over-attributed to the program.
The test has also been gamed in the other direction: a system can pass by being boring, by deflecting, or by making plausible errors. Human-likeness is not intelligence, and the two can diverge sharply.
The test measures the wrong thing, but it measured something. It made machine intelligence an empirical question at a time when it was purely speculative, and it forced the field to define behaviour rather than essence.
Passing it proves fluency and social modelling. Those are real capabilities, and they are what make language models useful — they are just not the thing the original question asked about.
The deeper objection is Searle's: a system can produce indistinguishable output while understanding nothing. If so, the test was always a test of the interrogator.
The archive labels this live debate because the operational and the metaphysical readings are both still in use, and the recent results have made the difference visible.
Why it is in the archive
Because 'it passed the Turing test' is now a marketing claim and a dismissal at once, and the paper itself says something much more careful than either.
Related: the Chinese room, stochastic parrots or world models.
Sources for this page
- Wikipedia, “Turing test” — the proposal, variants and criticismen.wikipedia.org
- Turing (1950), Mind — “Computing Machinery and Intelligence”doi.org
- Wikipedia, “ELIZA effect” — why fluent text is over-attributeden.wikipedia.org
- Wikipedia, “Loebner Prize” — the competitions and their criticsen.wikipedia.org